Delivery delays often come from how work waits between teams, not from a lack of capable people.
The meeting starts with a familiar proposal: add engineers. A roadmap has slipped, customers are waiting, and every team can name more work than it can finish. Hiring may be the right decision, but it is not yet a diagnosis. If work is ageing in queues between teams, another capable person may simply feed the same queue faster.
The practical question is where committed work waits after someone has finished their part. Handoffs, approvals, shared specialists, and unclear decision owners are flow constraints; extra staffing does not remove them.
A hiring plan is sound only when capacity is the constraint, not when capacity is the most visible explanation. The distinction matters because the business pays for a mistaken constraint call through commitments that move later and later; engineers pay through status meetings, escalations, and the coordination work required to explain why nothing is ready.
The competing remedies
Adding capacity and repairing flow are not opposing philosophies. They solve different problems, and a good decision makes the condition for each explicit. The decision spine is constraint type, not a preference for smaller teams or more process.
| Decision | What it can fix | What it cannot fix | Who pays if it is the wrong call | Early signal to inspect |
|---|---|---|---|---|
| Add capacity | A sustained shortage of people with the needed skills to perform work | Approval delay, unclear ownership, a specialist queue, or work repeatedly returned for decisions | The business carries a larger cost base; engineers inherit more coordination paths | Work begins promptly and remains active, but too much is genuinely in progress for the available skilled people |
| Repair the flow | Waiting caused by handoffs, review gates, shared dependencies, and contested priorities | A real shortage of a scarce capability or an unavoidable volume increase | Leaders spend attention clarifying ownership and stopping lower-value work; teams change familiar routines | Work spends long periods untouched between identifiable steps |
| Sequence both | A capacity limit that is real, while preventing new people from entering a broken route | Neither problem immediately; it requires disciplined observation | Everyone accepts a short period of focused measurement before a larger commitment | One queue remains after a narrow flow intervention, with active work still exceeding available skill capacity |
The table makes one point clear: more people increase the cost of ambiguity. Each new handoff adds a route for a decision to wait and another interpretation of who owns the next move. Hiring is valuable at a proved throughput limit, not as relief from an unexamined operating model.
The trade-off is real. Repairing flow asks leaders to name decision rights, reduce simultaneous priorities, and move ownership closer to the work. That can expose disagreements that a requisition postpones. It also makes the decision path easier to reason about, which is why consulting on delivery constraints should start with the decision path rather than the organisation chart.
The waiting path through the organisation
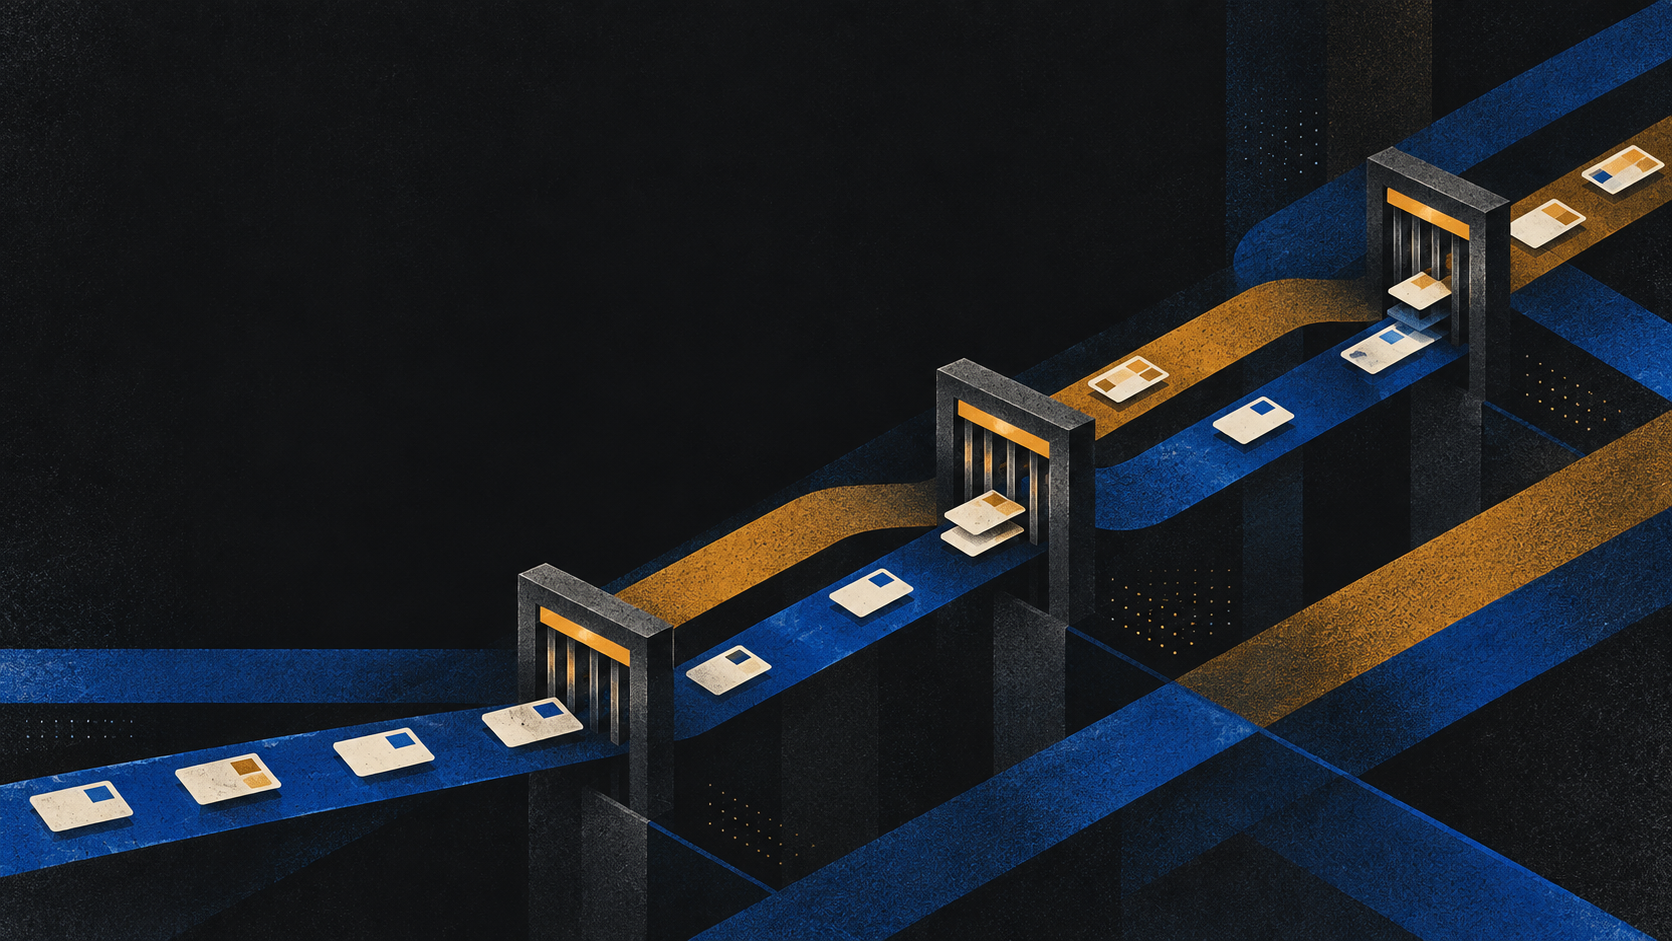
A delivery system rarely announces its bottleneck. Activity stays high: tickets move, meetings happen, and dashboards show progress. Queue age tells a different story because it asks how long an item has waited without its next decision or action, rather than how much work people have touched.
The diagram is deliberately simple. It shows a common route where implementation completes, then waits for a cross-team review and an approval that has no named decision owner. The problem is not that review or approval exists. The problem is an unowned approval path in which nobody is accountable for making the work leave the queue.
flowchart LR
    A[Committed work] --> B[Team implementation]
    B --> C{Cross-team handoff}
    C --> D[Review queue]
    D --> E{Approval owner named?}
    E -- No --> F[Decision waits]
    F --> G[Commitment slips]
    E -- Yes --> H[Release or next step]
A handoff is a management event, not just a technical boundary. Count each moment when a different person or group must understand enough context to move work forward. Then ask who can approve the next decision, what information they need, and what happens when they are unavailable. A queue with no explicit answer is a policy constraint even when every individual involved is working hard.
This is also where the approval path enters the architecture conversation. Systems that are difficult to reason about often require more coordination before anyone can change them safely; simple architecture under pressure is not an aesthetic preference when it removes the approvals and specialist interpretation a change otherwise needs. The useful unit of inspection is the path from commitment to release, not the productivity of any one team.
The capacity diagnosis
A capacity bottleneck has a different signature. Work reaches the people with the required skill promptly, stays active while they do it, and remains numerous enough that adding a qualified person would reduce the amount of unfinished work. Active demand exceeds available capability; it is not merely waiting for a decision elsewhere.
That diagnosis should be specific. “Engineering is overloaded” combines discovery, implementation, review, release, and support, then treats the total as evidence. Use stage-level evidence: separate the stages. A platform engineer may be capacity-limited while feature teams lose days to an approval committee. Hiring for the first can be sensible; hiring for the second gives the committee more people to delay.
A shared specialist can create either condition. If the specialist is continuously doing scarce work that no one else can safely perform, capacity is credible. If their calendar is consumed by re-explaining context, adjudicating priorities, and waiting for requests to become complete, the specialist is carrying a flow failure. The remedy may be clearer intake criteria, delegated decision rights, or pairing that spreads knowledge—not automatically another seat.
Leaders should resist treating utilisation as the verdict. A fully occupied person can be the symptom of a queue designed around them. The decision is better made from the work’s history: when did it enter the stage, when did somebody act on it, when was it returned, and what decision released it? Capacity is a condition to prove in the work path, not an impression collected in the planning meeting.
The reversible intervention
A large reorganisation is hard to reverse because it changes reporting lines, incentives, and the social contract around ownership. Hiring is also sticky: the commitment is sensible only if the constraint remains after the team has seen the work clearly. Run a narrow experiment first that changes one route without pretending to solve the whole organisation.
Choose one recurring delivery path and map its handoffs. For a short, defined period, give one accountable person authority to resolve a named approval, set a clear rule for what enters the queue, and limit the number of items allowed to wait there. Do not turn this into a reporting ritual. The test exists to see whether work moves differently through one route with an owner.
The result guides the next decision. If queue age falls and commitments move while the same people do the work, the primary problem was flow. If the queue clears but skilled work remains continuously active and backs up again immediately, the remaining constraint is now more likely capacity. The sequence preserves options: improve the route, then hire against the constraint that remains.
The intervention has a cost: making scarcity visible. A leader must make a priority explicit and tell another stakeholder that their request will wait. That is harder than approving headcount because it makes scarcity visible, but cheaper than building a larger organisation around an unclear route.
FAQ
When is hiring the right response?
Hiring is appropriate when a required capability is persistently occupied with active, well-defined work and the work starts promptly once it reaches that capability. The evidence is a sustained capacity limit, not a general sense that teams are under pressure. Keep checking that the added role will enter a clear route rather than a queue with no owner.
What should we measure on Monday?
Pick one committed item and record each handoff, the age of every wait, and the person authorised to release the next decision. Start with one path, not a programme-wide dashboard. The first aim is to make waiting visible enough to distinguish it from doing.
Does a matrix organisation always make delivery slow?
No. A matrix can work when decision rights and interfaces are explicit. Delay appears when shared accountability becomes unowned accountability—when several groups must agree but no one has the authority or obligation to close the decision.
How long should a reversible intervention run?
Run it long enough to observe several instances of the same route, not until it produces the preferred answer. Use a pre-agreed review point tied to the work entering that queue, then decide whether the pattern changed and whether the remaining constraint is actually capacity.
This week, take one stalled commitment from the roadmap, trace its waits from promise to next action, and name the person who can release the longest wait before opening the next headcount request.