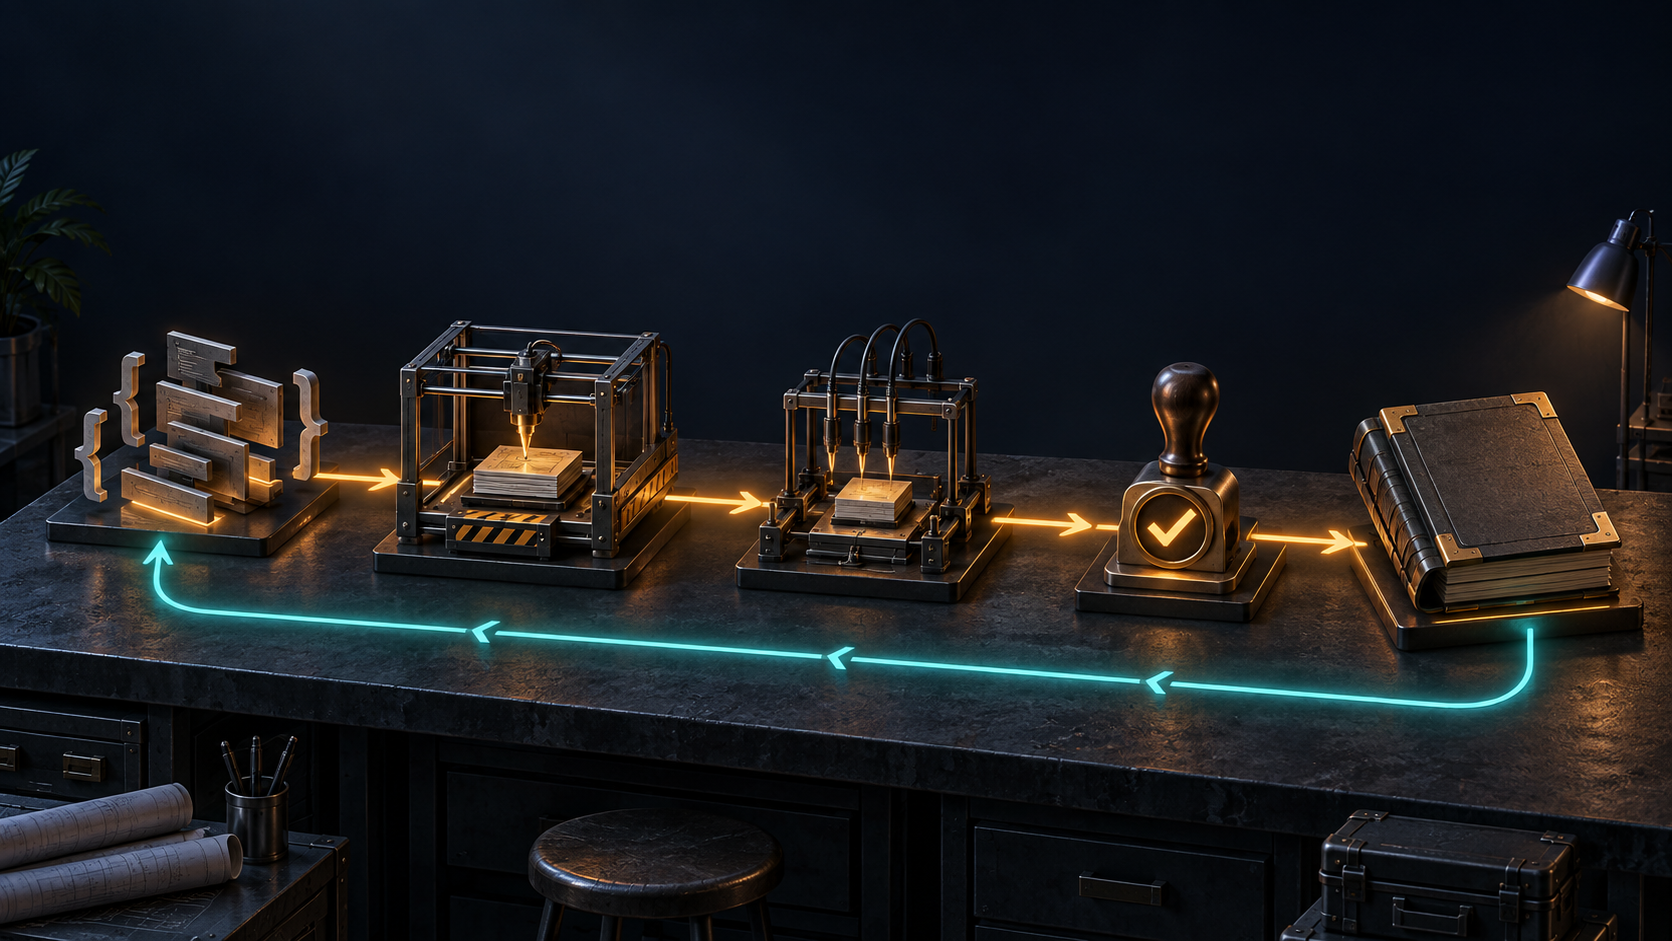
Adopt AI workflows whose results engineers can check independently, and keep those that shift hidden work into review and maintenance out of the team standard.
AI workflow adoption and the unexplained diff
The AI-written PR passes every check, but its author can’t explain why the parser now accepts an input it used to reject. In the team discussion, the demo says the workflow is ready; the reviewer says the behavior is still a mystery.
Make independently checkable tasks repeatable before approving broad autonomous coding. A useful workflow leaves behind a result another engineer can evaluate and knowledge the team can reuse. Prompt speed alone buys neither.
The cost doesn’t disappear when generation finishes. It moves to review, correction and maintenance if engineers must reconstruct the reasoning before they can trust the change. Treat each workflow as a separate adoption decision:
| Workflow | Verification effort | Reusable team knowledge | Failure mode | Adoption condition |
|---|---|---|---|---|
| Repository exploration | Check cited files, lines and execution paths | A corrected map of a subsystem | A plausible explanation of the wrong path | Claims stay tied to checked source evidence |
| Regression-test drafting | Establish expected behavior independently; check failure and correction | A protected behavior and a failure example | Test and implementation share the same mistake | The engineer owns the expected result |
| Behavior-preserving refactoring | Check the stated invariants and relevant contracts | Clearer structure plus explicit boundaries | Green tests hide a contract change | Scope and preservation checks are bounded |
| Review-summary drafting | Reconcile the summary with the actual diff | A navigation aid for later reviewers | Relevant changes disappear from the summary | The summary never substitutes for diff review |
| Open-ended implementation | Establish requirements and inspect the whole result | Uncertain until assumptions are resolved | Output grows faster than review capacity | Verification and permissions can be bounded first |
The table’s dividing line is the cost of establishing correctness, not how impressive the output looks.
Regression tests and the cost of a shared mistake
Test drafting is a strong trial candidate when the bug and expected behavior already exist outside the model’s answer. It isn’t strong merely because a generated test passes against generated code. Both can agree on the same wrong interpretation.
Consider an illustrative parser bug: malformed input should be rejected, but the buggy version accepts it. An engineer first establishes that expectation from the contract and independently reproduces the acceptance. The tool then drafts the regression test; it doesn’t decide what valid input means.
The reviewer checks that the test fails against the buggy version for the intended reason and passes with the correction. A failure caused by a missing fixture proves nothing about the parser. A test that asserts only that parsing returns something may pass both versions and protect nothing.
The reusable output is the test plus the reason rejection matters. That might be a documented input rule or an existing caller’s expectation. Keeping that basis attached prevents a later cleanup from treating the assertion as arbitrary.
Use this workflow when test construction is the laborious part and the expected behavior is clear. Restrict it when the task is really a requirements dispute dressed up as a test request.
Repository exploration and review summaries as navigation
Exploration can reduce search work, but a repository explanation remains a hypothesis until someone checks its references. Ask for the files and lines supporting each claim, then inspect the path relevant to the task. A class with the right name may not be the implementation the application uses.
Store corrected findings where engineers already look for subsystem knowledge. A prompt that repeatedly produces the same misleading map isn’t a team asset; a checked map with a known limitation can be.
Review summaries deserve a different boundary. Their job is to help a reviewer navigate, not determine whether the change is safe. Compare the summary with the diff, especially changed defaults, error paths and configuration. An omission can matter more than a false statement because it directs attention away from the risky change.
This is why AI code review needs explanation rather than trust: the author must account for the behavior, even when a tool supplies the description. Keep summaries optional if reconciling them costs more effort than reading the diff directly.
Bounded refactoring and incomplete preservation checks
A narrow refactor is eligible, but green tests don’t establish that every relevant contract stayed intact. Tests may omit error behavior, ordering, public signatures or side effects that callers depend on.
Write down the invariants before generation: for example, the same inputs produce the same results and errors, with no change to the public API. Identify any additional checks those claims need. If the proposed cleanup changes a default or adds a dependency, it has crossed into a different decision.
The trade is less repetitive editing for more explicit preservation work. The author pays that cost before the reviewer does. Without the boundary, the reviewer has to infer which changes were intentional and which came along for the ride.
Prefer a local change you can revert independently. If preserving behavior requires understanding several poorly documented subsystems, begin with exploration rather than approving the refactor workflow on faith.
Open-ended implementation and unbounded review
Broad implementation needs a higher burden of proof because it creates both the change and assumptions about what the change should do. More generated output can create more work when each claim needs an engineer to reconstruct its basis.
Approval would require believing that acceptance criteria are independent, the diff remains inspectable, and the tool’s permissions fit the task. A convincing demo doesn’t establish those conditions. Leave broad automation unapproved if verification cost or access cannot be bounded; that doesn’t prohibit private exploration within existing rules.
A tool allowed to run commands needs explicit permissions, not implied permission from a coding request. Define allowed context, exclude sensitive inputs, prohibit production writes, and keep approval with an engineer. Self-approval removes the independent decision this workflow needs.
A reversible trial and a reusable handoff
Trial one task class, with a named owner and a review date, before declaring a standard. Describe the ordinary route without AI so the team can compare complete change cycles rather than keystrokes. Include review, correction, debugging and maintenance observations; don’t turn impressions into an ROI figure.
Agree on stopping conditions before the first result: scope expansion, prohibited inputs, claims nobody can verify, or review and rework beyond the effort the team agreed to spend. Stop the trial task when one occurs rather than widening its permission after output already exists.
The handoff needs evidence, not a full chat archive:
- Task and invariant: what was requested and what must remain true.
- Context and limits: what the tool could see or do, and what was excluded.
- Proposed diff: the change an engineer is being asked to accept.
- Executed checks and observations: what actually ran, what happened, and what remains unchecked.
- Author decision: accept, revise or reject, with unresolved limits recorded.
A second engineer should be able to re-evaluate without the original author. Preserve shared failure notes and adjust task boundaries when the evidence warrants it. Those corrections compound; a library of canned prompts alone doesn’t.
At the review date, choose retain, restrict or discard. Retaining the workflow means keeping its boundaries, not approving adjacent tasks by association. Team AI training should make this judgment repeatable, including the ability to stop using a workflow that shifts work downstream.
FAQ
Can we start when the repository has no reliable tests?
Start with checked exploration, not a behavior-changing task that relies on a weak suite for acceptance. A regression-test trial is still possible if an engineer can independently reproduce one failure and establish its expected result; that doesn’t make the rest of the suite trustworthy.
What about sensitive repository inputs?
Set the input boundary first, using the organization’s approved tools and data-handling rules. Secrets, customer records and restricted code remain excluded unless explicitly authorized; substituting synthetic examples can help, but may also remove context the task needs.
Does a model or vendor change invalidate approval?
Revalidate affected workflows when the model, vendor, repository context or tools change. Revisit the checks and permissions the approval depended on; the old workflow name isn’t evidence that the new setup behaves acceptably.
Is this too much documentation for a small team?
Put the evidence in the PR rather than creating a parallel reporting system. Routine private exploration needn’t become policy, but a team standard needs enough recorded basis for another engineer to challenge it.
Choose one bounded task, define its independent check and stop condition, and have another engineer inspect the first result before making it a team practice.