Trace AI-assisted changes through review, release queues and rework to distinguish faster drafting from faster delivery, without mistaking activity for value.
The fast PR and the slow delivery
The AI-written PR passes its checks, the author says it was quick, and the reviewer still can’t explain why the change works. More code is ready. Delivery hasn’t caught up. Authoring speed and delivery speed have parted company, but a dashboard counting generated code would call the trial a success.
Measure the change through review, merge and production deployment, then inspect the corrections that followed. Keep author time as a local diagnostic, not a substitute for that chain. A tool can reduce the effort of drafting an implementation while transferring work to the person who must establish that it’s safe.
This isn’t a verdict against AI assistance. Earlier completion can create room for better tests or an explanation that makes review easier. It can also create a larger batch that takes longer to understand. The useful question is which workflow improved for which class of change, not whether the team became universally more productive.
Deployment is a concrete delivery marker, but not proof of user benefit. A change behind a disabled flag may be deployed without being released. Record that distinction rather than presenting an infrastructure event as a customer outcome.
The queues between generation and deployment
Generation changes one part of a larger system. Local service time is time spent doing a particular activity; end-to-end elapsed time also includes waiting between activities. Finishing preparation sooner only brings delivery forward if the remaining path can take advantage of it.
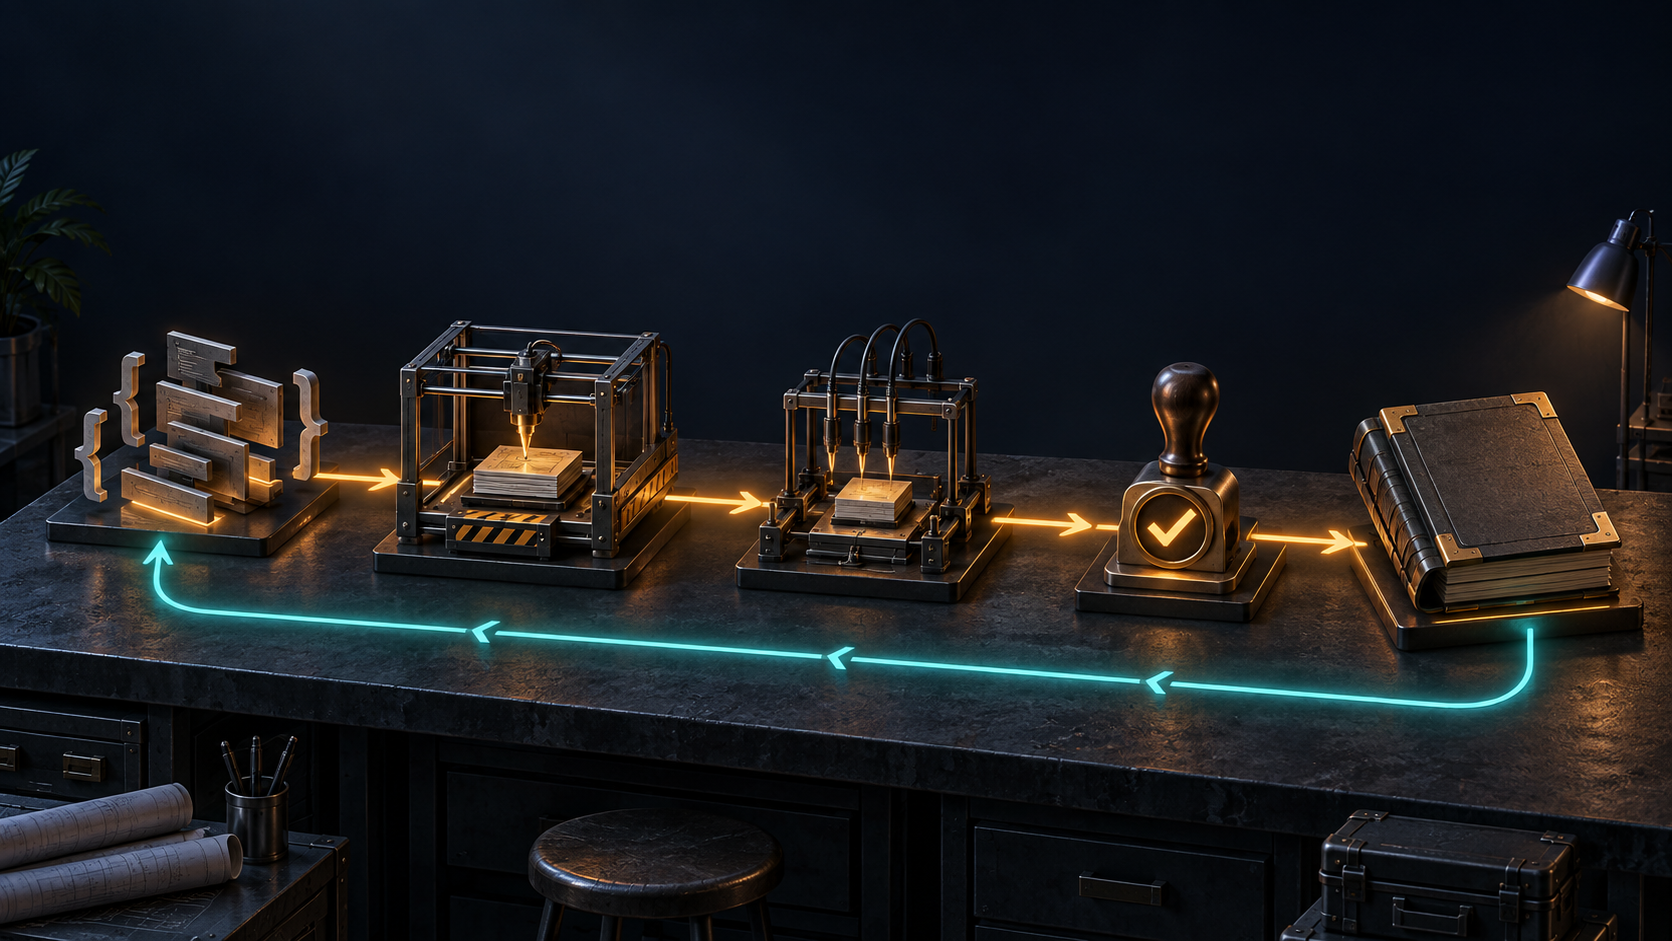
The diagram follows a change through that path. Preparation produces review-ready code; review can send it back for correction. Merge still leaves release waiting, and deployment can expose failures that create more work. Neither loop disappears at PR approval.
flowchart TD
    A["Task started"] --> B["Preparation and generation"]
    B --> C["Ready for review"]
    C --> D["Review and correction"]
    D -->|"Revision needed"| B
    D -->|"Approved"| E["Merged"]
    E --> F["Release wait"]
    F --> G["Production deployed"]
    G --> H{"Failure or rework observed?"}
    H -->|"Yes: follow-up change"| B
    H -->|"No"| I["Continue observing outcomes"]
A reviewer with a full queue doesn’t become available because an author finishes early. If generation increases the arrival of changes without increasing review capacity, waiting can absorb the saving. If a release window is fixed, a preparation improvement may matter only when it lets a change catch an earlier window.
This is why delivery problems often come from team structure: ownership boundaries, review access and release decisions shape the path the code must travel. Measuring only the editor excludes those constraints without making them less real.
Keep work and waiting distinct. Review-ready-to-merge includes queueing, active review, author revisions and fresh waits. Its duration tells you where to investigate; timestamps alone cannot tell you which activity consumed it.
The activity metrics that hide transferred work
An activity counter records what a tool makes easy to count. It doesn’t establish delivered value or avoided effort. Accepted suggestions may replace typing, produce unnecessary code, or require later correction. PR counts can rise because changes were split differently, even when the delivered scope stays unchanged.
Use each signal for a decision it can support. The matrix separates evidence of activity, evidence of flow and evidence of quality; none deserves to become an individual performance target.
| Signal | Useful decision | Limit |
|---|---|---|
| Tokens, lines, accepted suggestions, PR counts | Whether a workflow is being used | Activity isn’t delivered value |
| Author’s active time | Where preparation effort changed | Excludes reviewer effort and waiting |
| Whole-chain elapsed time and stage intervals | Where delivery appears delayed | Shows flow, not the cause of delay |
| Escaped defects and corrective work | Whether a quality guardrail is holding | A defect isn’t automatically AI-attributable |
| Author and reviewer feedback | Which friction deserves investigation | Explains experience, not elapsed duration |
Transferred understanding is a particular failure mode. The author accepts an implementation without building enough understanding to defend it, so the reviewer reconstructs the reasoning. The right response is code review that requires explanation rather than trust, not a reward for how quickly the PR appeared.
A shorter interval can also be the wrong comparison. Routine changes and risky migrations don’t share a meaningful baseline. Nor do changes under different review policies or release cadences. Keep task class, repository and risk comparable, and record differences in batch size rather than hiding them in an average.
Simple before-and-after measurement still cannot establish causal uplift. Staffing, calendar effects and process changes may explain the difference. Self-selected AI use adds another problem: engineers may choose assistance for tasks already likely to go quickly. Report the observed pattern and its uncertainty, not a tool-attributable percentage the design cannot support.
The timestamp trail and its blind spots
Start with four explicit events: task started, review-ready, merged and production deployed. Define task start consistently before collecting data. If one record starts at assignment and another at the first edit, their apparent preparation times describe different boundaries.
Use timezone-aware timestamps and preserve their source. A PR event can establish review readiness; a deployment record must identify when the relevant change reached production. Elapsed intervals are not person-hours: they include nights, weekends and waiting, and they don’t reveal how many people worked in parallel.
This helper calculates adjacent intervals in seconds. It is illustrative instrumentation, tested with synthetic fixtures for correct deltas, missing fields, absent timezones and out-of-order events. Those tests validate the helper’s behaviour; they produce no observations about a team’s productivity.
from datetime import datetime


def elapsed_stages(events):
    names = ("started", "review_ready", "merged", "deployed")
    times = [datetime.fromisoformat(events[name]) for name in names]
    if any(t.tzinfo is None for t in times):
        raise ValueError("Timezone required")
    if any(right < left for left, right in zip(times, times[1:])):
        raise ValueError("Events out of order")
    return {
        f"{left}_to_{right}": (end - start).total_seconds()
        for left, right, start, end in zip(names, names[1:], times, times[1:])
    }
The caller supplies complete, ordered events. A missing field raises an error rather than silently removing a difficult task from the analysis. Handle that error by reporting the missing evidence, not by replacing the duration with zero. Keep open, abandoned and interrupted tasks visible separately; completed changes alone can make a stalled workflow look healthy.
These intervals are not DORA change lead time. DORA defines change lead time as commit-to-production, not task-start-to-production. Its guidance also stresses application or service context and warns against disparate comparisons and a single metric target.
A summary record cannot preserve repeated events. If review readiness was withdrawn, a change reopened, or deployment triggered corrective work, retain an event history alongside the first-pass timings. Record reviewer corrections as evidence of rework; don’t add overlapping elapsed intervals and call the result labour cost.
For a suspicious stage, reconcile the record with both author and reviewer. Establish whether it reflects a queue, missing context, a failed test, revision work or a release hold. A clock locates the interval. The conversation supplies a hypothesis you can check against the artifacts.
The bounded trial and the adoption decision
Choose one application and a comparable task class before drawing conclusions. Build a baseline from real previous changes with recoverable evidence. If those records don’t exist, start prospective logging; a remembered impression of earlier speed is not a replacement dataset.
Give the trial an owner, review date and definition of done. Agree on a quality guardrail and the decisions the evidence can change: continue the workflow, restrict it to a narrower task class, or stop it. Record staffing changes, interruptions, review-policy changes and release constraints alongside the observations.
Keep collection proportional to the decision. Workflow timestamps, a coarse assistance label and short explanations of corrections may be enough to discover that review is the constraint. Prompt surveillance and a new analytics platform add cost without necessarily making attribution more honest. Authors and reviewers pay that collection cost in time away from delivery.
Interpret the stages together. Preparation down, review up is a reason to inspect transferred effort, not immediate proof of harm. Delivery down, rework up calls for the quality guardrail. Unchanged deployment timing with less active effort may still be useful, but it supports an effort claim, not a delivered-speed claim.
The point of choosing AI workflows deliberately is to make adoption conditional on evidence the team can inspect. In practical AI training, that includes the ability to explain the generated change and recognise when assistance has moved work downstream. The measurement should support that practice, not rank developers by their tool usage.
FAQ
Can a small team learn anything with so few changes?
Yes: traceable cases can identify missing events, repeated corrections and release holds. They don’t justify a universal productivity claim; keep the observations attached to their context instead of promising statistical certainty from a small sample.
What if production deployment timestamps are unavailable?
Report the path only to the last verified boundary, such as merge, and label it accordingly. Identify what would connect commits to deployment records; don’t infer production delivery from an approved or merged PR.
Do we need to retain prompts to measure assistance?
Not for these intervals. Prefer an agreed coarse workflow label and minimal metadata, with access and retention rules; sensitive prompts and customer information needn’t become measurement material.
What if the tool or review process changes during the trial?
Mark the change and separate the periods rather than blending them into a clean-looking result. If the change alters the task or workflow substantially, restart the comparison and keep the earlier observations as context.
For the next bounded, comparable change, trace task start through deployment, reconcile the intervals with its author and reviewer, and record the missing evidence before saying AI made delivery faster.